Jev-guided sparse attention for MiniMax H3
Jev selects a sparse-attention rate for each layer during video generation. The author reports a run falling from 6m07s to 3m34s on an RTX 4070.
Tweet not found
The embedded tweet could not be found…
Jev selects a sparse-attention rate for each layer during video generation. The author reports a run falling from 6m07s to 3m34s on an RTX 4070.
The embedded tweet could not be found…
I made Jev talk and wrote a paper on it. To publish it on arXiv, I need an endorser for csCL fom someone who has 3+ arXiv papers in any cs category, submitted between 3 months and 5 years ago. It's one click after I DM you the code and the paper. Or maybe someone you know. A
@xucian_ · Research & data

@xucian_
X post
Research & data
-
-
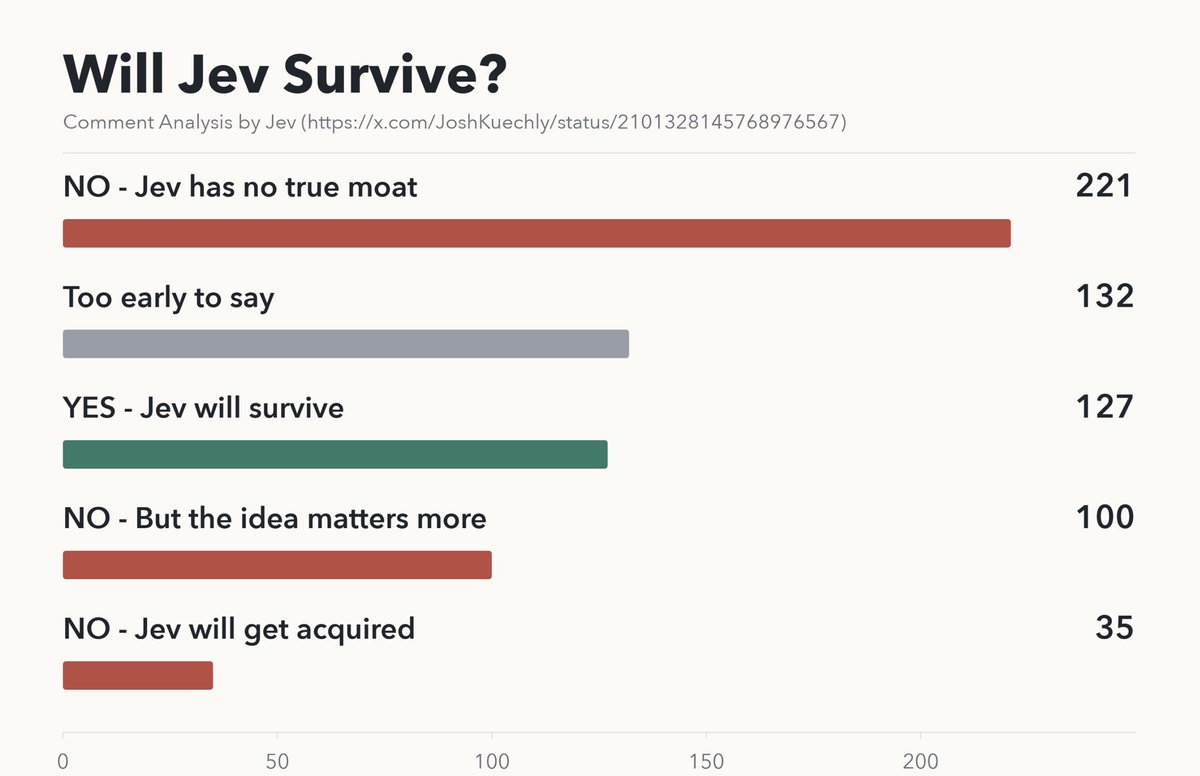
I asked Jev to predict its own future. My last post (below) got 300k+ impressions, 400+ comments, 101 reposts. I used Jev to categorize every comment and quote to capture public X opinion on Jev’s future. Here’s results: ———— *Note: I created five prediction buckets,
@JoshKuechly · Research & data

@JoshKuechly
X post
Research & data
-
-
I built an ultra-fast medical simulation with Jev and Grok 4.7 Grok 4.7 and I co-doctored a cancer patient across 20+ possible futures in just minutes. Grok proposed the moves. Jev ran the high-speed state decisions < 0.3 secs Patientic visualized the branched outcomes. 🧵👇
@chris_not_busy · Research & data
@chris_not_busy
X post
Research & data
-
-
Built a small experiment to understand my chess beyond “blunders” and “accuracy.” https://t.co/vJlJFW03dj games → Stockfish for objective move analysis → Jev for recurring semantic patterns → code for trends and loss/win comparisons. Now the dashboard can show what keeps
@ankitatr_ · Research & data
@ankitatr_
X post
Research & data
-
-